Tags

#Simd

3 posts

Low-Latency Systems Development #15 10 min read

SIMD Vectorization and Intrinsics

One instruction computes a row of numbers only if the compiler knows how wide a register it may use, is sure nothing overlaps, and is allowed to reorder; when it can’t get all three, intrinsics let you write it yourself, at the …
Low-Latency Systems Development #9 21 min read

Loop Optimization

A dot-product loop reports “vectorized” at -O3, yet its four additions still wait on each other: floating-point addition isn’t associative, so the compiler won’t reorder it. What loop optimization really asks of you is to spot …

Low-Latency Systems Development Topic 36 min read

Memory Latency and Bandwidth

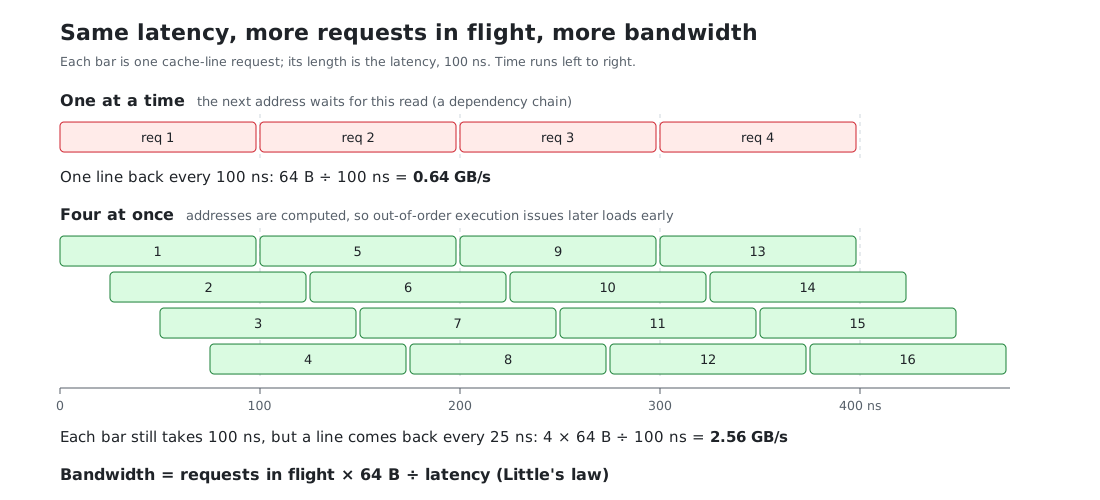
One memory access takes about 100 ns and brings back 64 B. One at a time, that’s 0.64 GB/s, yet one core reading sequentially gets 15–60 GB/s. The missing factor is the number of requests in flight. Whether the next load’s address …